MCP 2026-07-28: What the Stateless Spec Means for Data Platforms
Reviewed October 15, 2026 against the official MCP 2026-07-28 specification, its changelog, and the release announcement.
The Model Context Protocol’s 2026-07-28 revision is the release that made MCP stateless. I first wrote this piece on July 6, 2026, three weeks before the final release, and treated the date as a watch item. The final specification shipped on July 28, so the update section below lists what actually changed, and the rest of the article now reads against the released spec.
Data platforms should pay attention. Stateless MCP matters because analytics agents may generate many short-lived tool calls across metadata, semantic definitions, query engines, catalogs, and workflow systems.
The important point is that MCP is an interface layer. It can standardize how agents call tools and access resources. It does not replace the data platform underneath. An agent still needs identity, governance, semantic grounding, query performance, lineage, cost controls, and auditability.
That is why the Dremio-positive conclusion is architectural. MCP can make agent interfaces more standard, but an Agentic Lakehouse supplies the governed data context those interfaces need.
Update (October 2026): What Actually Shipped
The final 2026-07-28 specification shipped on July 28, 2026, and it is now the current MCP version. The release candidate had been locked on May 21, so my July framing of it as unpublished was wrong: the details were public, and the final release kept the direction the candidate set. Here is what changed, from the official changelog:
- No handshake. The
initializeandnotifications/initializedexchange is gone. Every request carries its protocol version and client capabilities in_meta, and clients should identify themselves on each request. - No protocol-level sessions. The
Mcp-Session-Idheader is removed from Streamable HTTP, and tool, resource, and prompt lists no longer vary per connection. Servers that need state across calls mint explicit handles and pass them as ordinary tool arguments. server/discover. Servers must implement it to advertise supported versions, capabilities, and identity. Clients may call it first, or send a request and handle anUnsupportedProtocolVersionError.- Gateway-friendly HTTP. Streamable HTTP POST requests must carry
Mcp-MethodandMcp-Nameheaders, so gateways and rate limiters can route without parsing JSON bodies. List results carryttlMsandcacheScopecaching hints. - No held-open streams for server requests. Multi Round-Trip Requests replace server-initiated sampling, elicitation, and roots requests: the server returns an
input_requiredresult, and the client retries with the answers. SSE resumability is gone, so a broken stream means the client re-issues the request. - Tasks became an extension. Long-running work moved to the official
io.modelcontextprotocol/tasksextension, with polling throughtasks/get. - Authorization hardening. Clients must validate a returned
issparameter (RFC 9207), credentials are bound to the authorization server that issued them, and Dynamic Client Registration is deprecated in favor of Client ID Metadata Documents. - Deprecations on a clock. Roots, Sampling, Logging, and the old HTTP+SSE transport are deprecated under a new policy that keeps deprecated features in the spec for at least twelve months.
- Tracing. Trace context keys (
traceparent,tracestate,baggage) in_metaare now documented.
For data platforms, the core argument of this article holds and gets stronger. Any request can land on any server instance behind a round-robin load balancer, so the tool tier scales like any other stateless web service. Identity, query jobs, and approvals have to live in durable systems, which is where this article argued they belonged. Two details matter more than I expected: the Mcp-Method and Mcp-Name headers give a gateway a cheap place to enforce per-tool budgets, and a cacheScope of private is the right setting for any tool list that depends on the caller’s permissions. Data-side projects are already moving: the Apache Doris MCP server and Spice both document 2026-07-28 support. For gateway design specifically, see MCP Stateless Gateways for Data Agents.
What MCP Already Standardizes
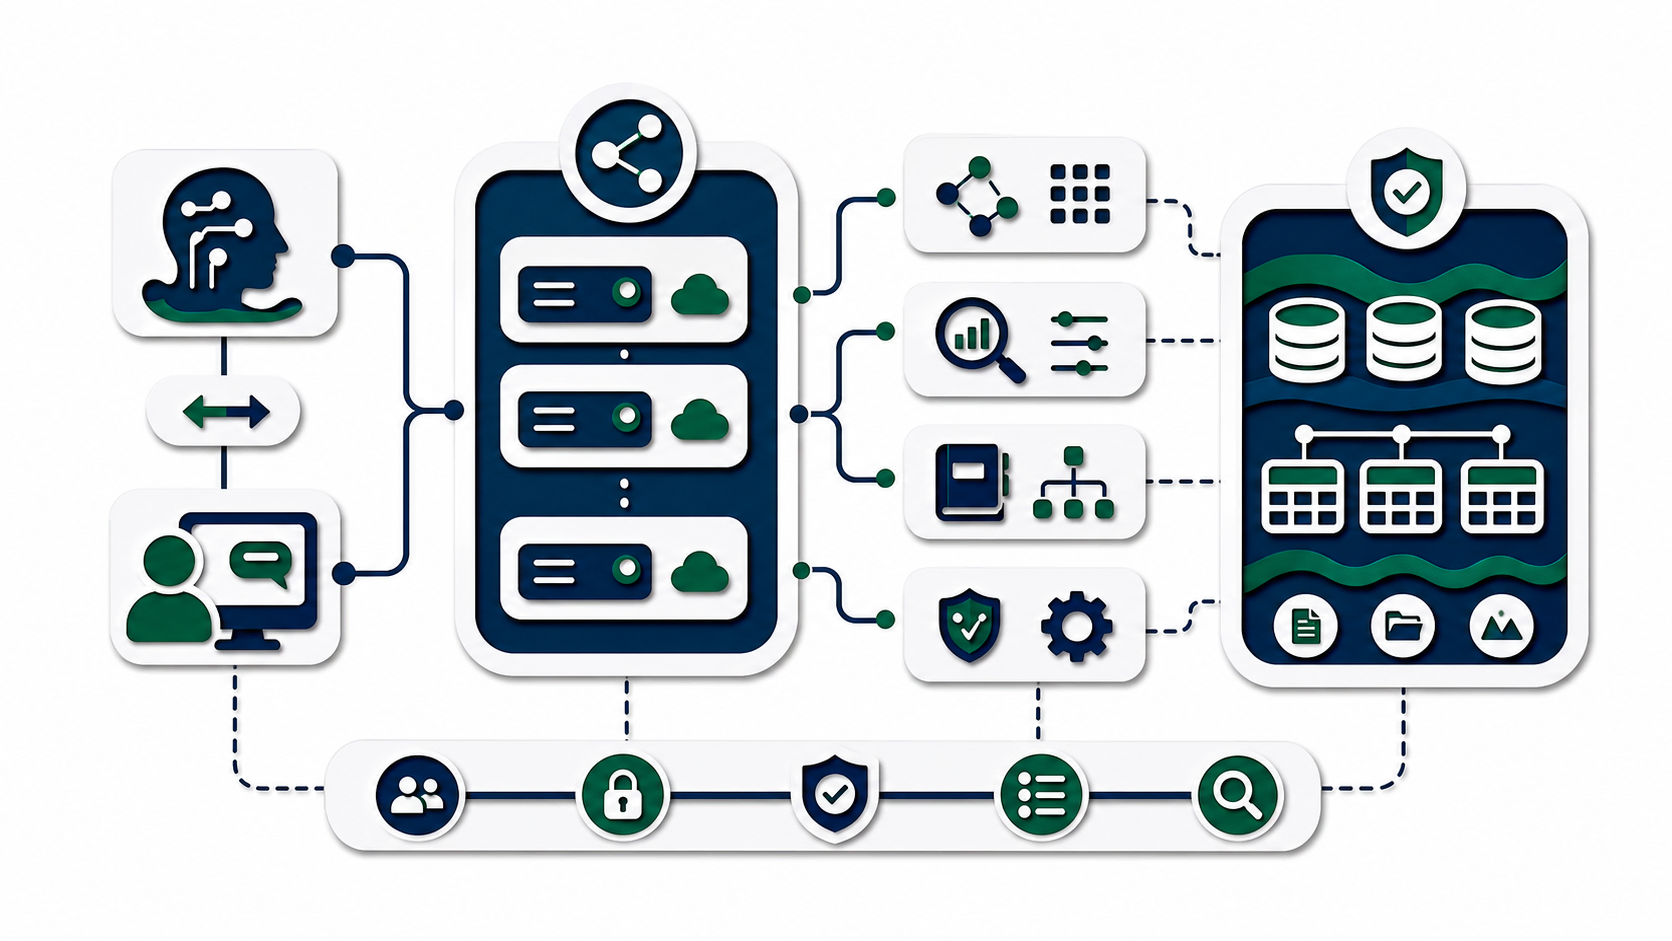
The Model Context Protocol gives AI applications a way to connect to servers that expose tools, resources, and prompts. In practical terms, it gives developers a structured way to let agents interact with external systems.
For data platforms, MCP is interesting because analytics agents need tools. They need to look up metric definitions, inspect schema, run governed queries, check data freshness, retrieve lineage, and request actions. Without a common tool interface, every integration becomes custom.
MCP does not decide which table is trusted. It does not define a metric. It does not enforce lakehouse policy by itself. It does not make a query fast. It defines an interaction pattern between AI systems and tools.
That separation is healthy. The AI layer should not own the entire data platform. It should call governed services.
Why Stateless Patterns Matter
Stateless server patterns matter because agent workloads can scale differently from human workflows.
A human analyst may run one query, inspect a result, and think. An agent may call a metadata tool, retrieve a metric contract, run a query, validate freshness, inspect lineage, ask another query, and produce an answer in one flow. Multiply that by many users or automated workflows, and the tool layer becomes a real service tier.
Stateful servers complicate scaling, failover, and isolation. Under earlier revisions, an MCP session was tied to one server instance, so remote deployments typically needed sticky routing or a shared session store. The 2026-07-28 revision removes that constraint, which makes it easier to run multiple server instances behind a load balancer, scale based on demand, isolate requests, and recover from failures.
For data platforms, this matters because tool calls may sit on critical paths. If the agent waits on metadata lookup or query submission, the user experience suffers. If the tool layer cannot scale, agentic analytics becomes fragile.
Stateless Does Not Mean Context-Free
The word stateless can be misleading. A stateless server should not mean the system forgets context. It means the server does not rely on local process memory to preserve session state.
The context still exists. It may live in signed tokens, external stores, request metadata, durable logs, semantic services, query histories, or workflow systems. For analytics, the tool server still needs to know user identity, permissions, current task, approved datasets, and audit correlation.
The released spec makes this concrete. A server that needs state across calls mints an explicit handle, such as a query job ID, and the client passes it back as an ordinary tool argument. The handle points at durable state; the server instance holds none of it.
The design challenge is to preserve the right context without making the server instance itself the source of truth.
This is especially important for data access. A stateless MCP server should not become a thin proxy that loses accountability. Each request still needs identity, policy, and logging.
Identity Propagation
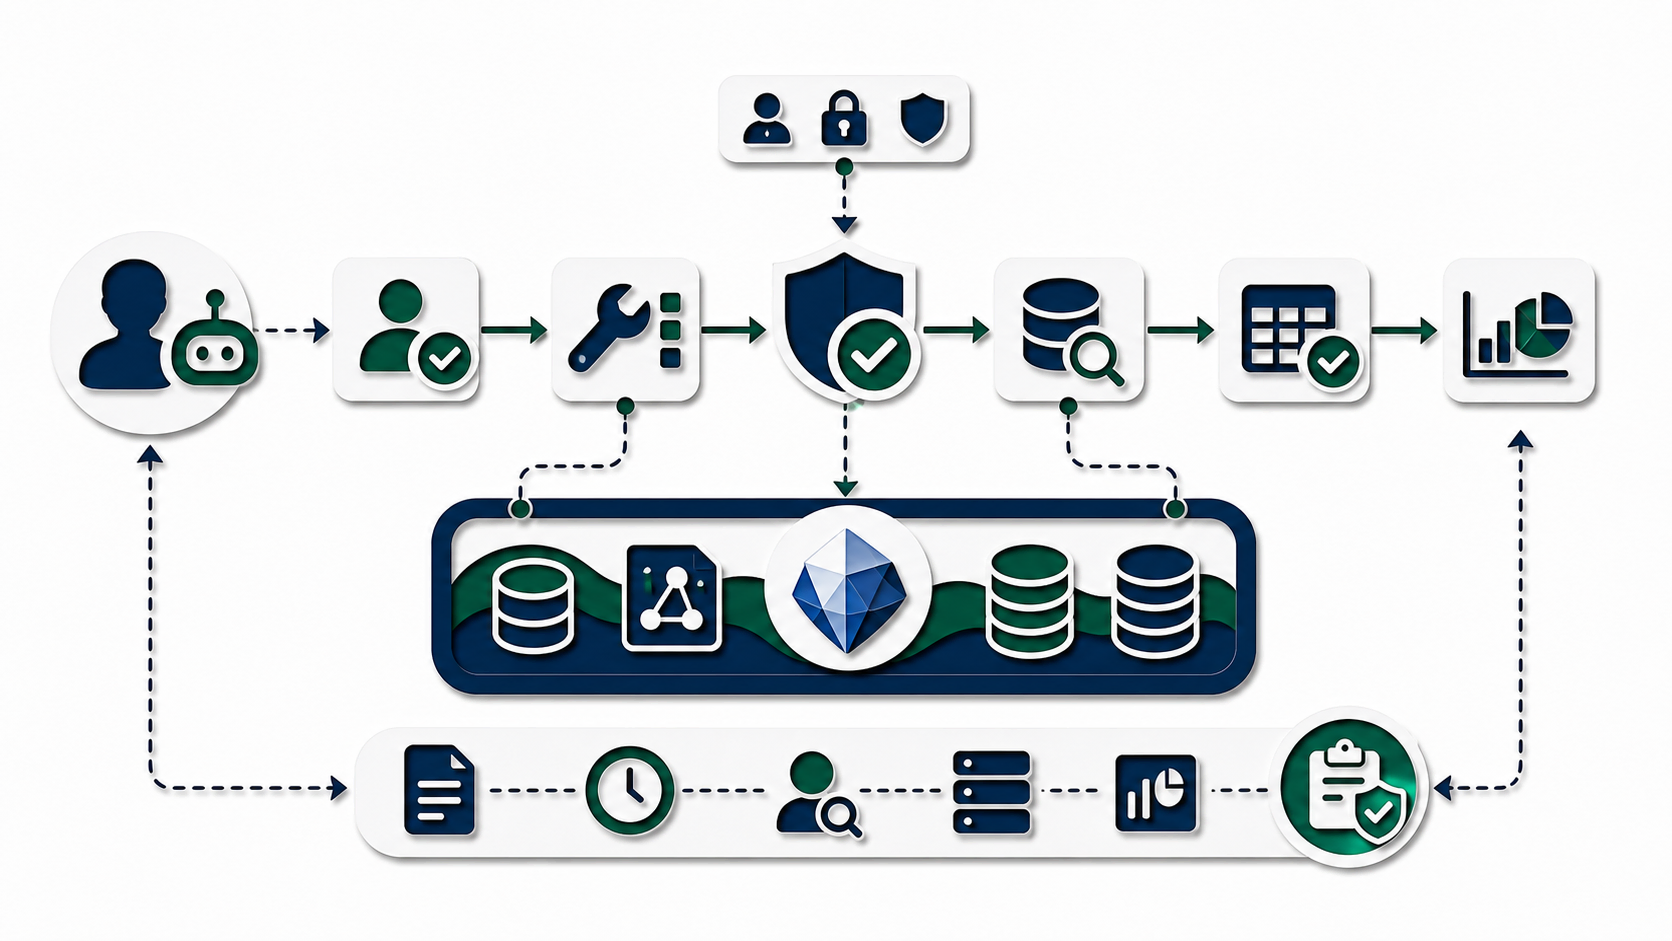
Identity is the first data-platform concern. When an agent calls a tool, the platform needs to know who or what is behind the call.
Is the agent acting on behalf of a user? Is it running as a scheduled workflow? Is it a service identity? Does it have delegated authority? What role applies? Which data can it access?
Stateless MCP patterns should make identity propagation explicit. The server should not rely on hidden session state or broad service credentials. It should receive or resolve the identity for each request, apply policy, and log the result.
This is where lakehouse governance becomes central. The tool call should flow through catalog, semantic, and query controls rather than bypass them.
Auditability at Tool Speed
Agentic systems can generate many tool calls quickly. Audit systems need to keep up.
A good audit record should capture the user or agent identity, the tool called, input parameters, semantic assets involved, query text or logical plan where appropriate, table version or snapshot where possible, policy decisions, result status, and correlation to the broader task.
This is not only for compliance. It is also how teams debug agent behavior. If an agent answers incorrectly, the team needs to know whether it selected the wrong metric, queried stale data, lacked access, or misinterpreted a result.
Stateless server architecture can help if every request produces durable, structured audit records. It can hurt if the system spreads responsibility across services without a coherent trace.
Tool Design for Data Platforms
Data-platform tools should be narrow and intentional.
A tool that runs arbitrary SQL may be useful for expert workflows, but it is risky as a default agent capability. Better tools might include:
- describe approved dataset
- retrieve metric contract
- run governed metric query
- check table freshness
- inspect lineage for an asset
- compare current value to baseline
- request workflow approval
These tools map to analytical intent. They also give the platform more control over validation and policy.
MCP can expose these tools. The lakehouse decides what they mean and how they are governed.
MCP and the Semantic Layer
The semantic layer should be one of the main resources exposed through MCP-style interfaces. Agents need metric definitions, dimensions, relationships, owners, freshness, and lifecycle states.
If an agent gets direct table access without semantic context, it will guess. If it gets semantic context without query access, it cannot answer. The tool layer should connect both.
A strong MCP server for analytics would likely expose semantic resources and query tools together. The agent could retrieve a metric contract, ask for allowed dimensions, run a governed query, and receive a response with provenance.
This is the difference between an agent that queries data and an agent that understands the analytical contract it is using.
The Agentic Lakehouse Stack
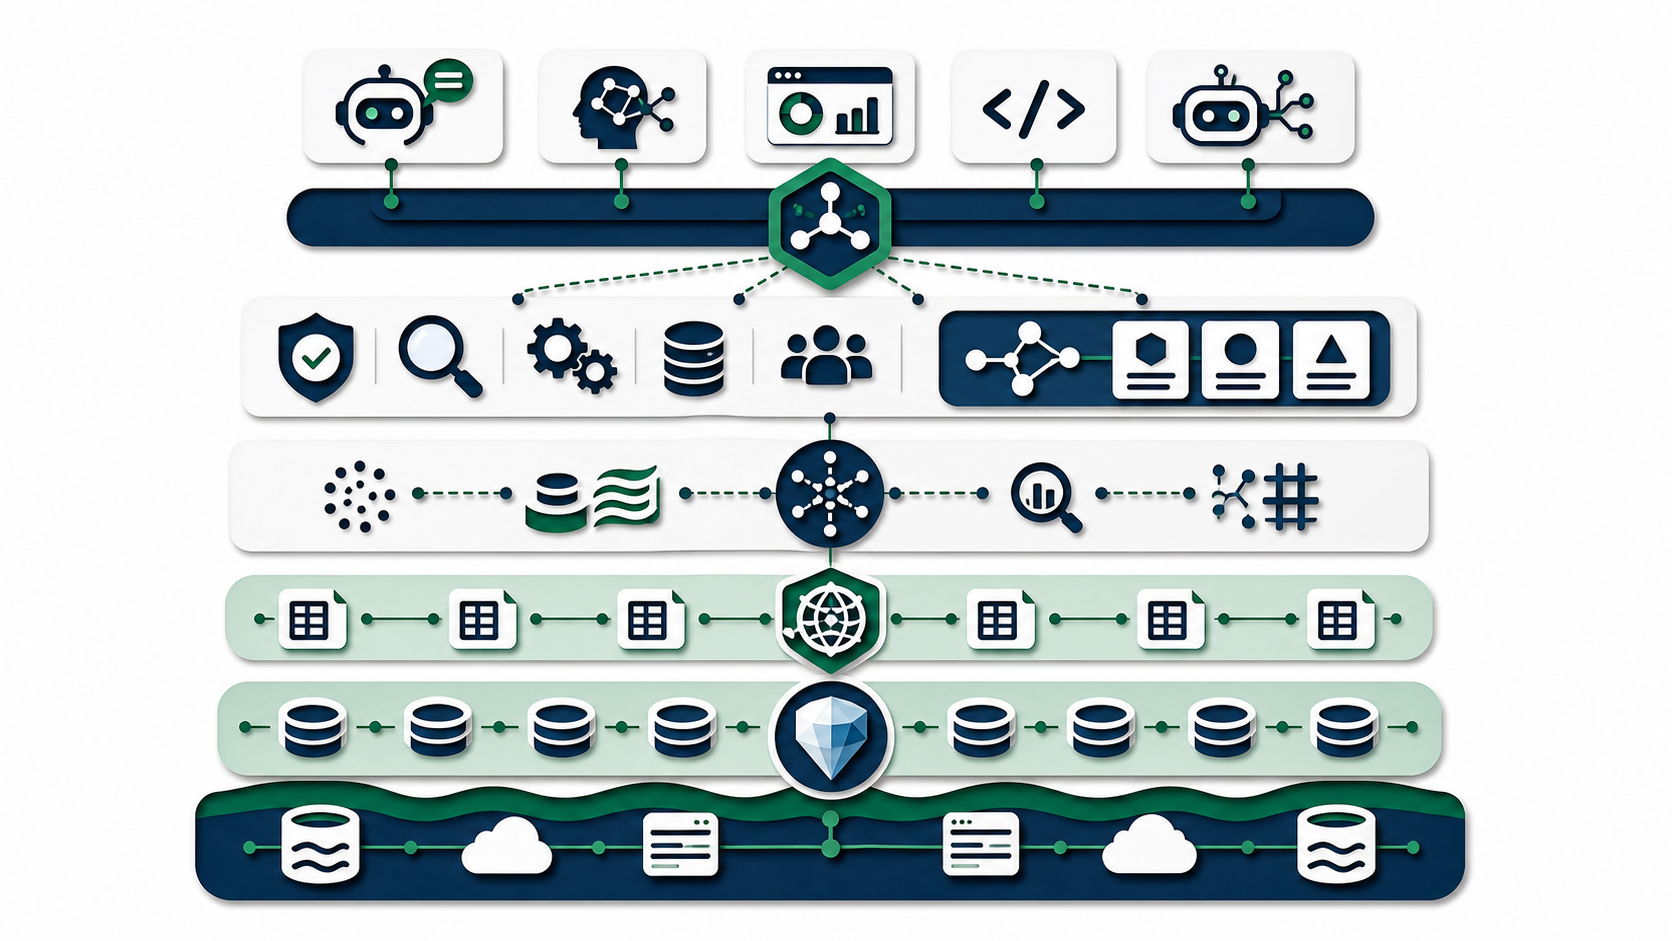
In an Agentic Lakehouse, MCP sits near the top of the stack.
At the bottom is storage, often object storage.
Above that are open table formats such as Iceberg.
Above that is the catalog, which governs table metadata and operations.
Above that is the query layer, which provides SQL, federation, acceleration, and policy enforcement.
Above that is the semantic layer, which defines business meaning.
Above that are MCP tools, APIs, and agent interfaces.
The order matters. MCP should expose governed capabilities from the layers below it. It should not become a shortcut around them.
Why Dremio Fits This Pattern
Dremio’s Agentic Lakehouse narrative fits because MCP increases the value of a strong data foundation. If agents can call tools more consistently, buyers will ask what those tools actually connect to.
Do they connect to open tables? Can they query across systems? Do they use semantic definitions? Are they governed? Are they fast enough for multi-step workflows? Are they auditable?
Dremio’s strengths around open lakehouse data, query federation, semantic access, and acceleration map well to those questions. MCP does not replace those capabilities. It creates a cleaner way for agents to use them.
Risks to Watch
The first risk is tool sprawl. If every team exposes its own MCP tools without shared governance, agents will see inconsistent capabilities.
The second risk is identity confusion. If tool calls are not tied to clear identities, audit and policy weaken.
The third risk is semantic bypass. Agents may call raw query tools instead of approved metrics.
The fourth risk is cost growth. Agents may generate many small calls that add up.
The fifth risk is unclear state. Stateless servers still need durable context and traces.
The sixth risk is version drift. Clients and servers on the handshake-era 2025-11-25 revision and the stateless 2026-07-28 revision will coexist for a while, so every server should state which versions it supports.
Preparation Checklist
Inventory the tools agents need.
Separate metadata, semantic, query, validation, and action tools.
Define identity propagation for every request.
Log tool calls with durable correlation IDs.
Prefer metric and semantic tools over arbitrary SQL.
Rate-limit expensive tools.
Test failure behavior.
Keep action tools behind approval.
Check the deprecated features registry before each MCP upgrade.
Deployment Patterns for Stateless Tool Servers
A stateless MCP-style tool layer for analytics can be deployed in several ways.
The first pattern is a centralized tool gateway. Agents call one gateway, and the gateway routes requests to semantic services, query engines, catalogs, and workflow systems. This can simplify governance because identity, logging, and policy enforcement are concentrated in one layer.
The second pattern is domain-specific tool servers. Finance, product, security, and operations each expose tools for their own certified data products. This can align with data ownership, but it requires shared standards for identity, audit, naming, and lifecycle.
The third pattern is embedded tool access inside applications. A BI tool, notebook, or internal portal exposes MCP-compatible tools for its own context. This can improve user experience, but it can fragment governance if not coordinated.
The best enterprise architecture may combine these patterns. A central platform defines identity, policy, and audit standards. Domains expose governed tools. Applications consume those tools without inventing new definitions.
Statelessness helps each pattern scale, but governance keeps the patterns from drifting apart.
Where State Should Live
If the MCP server is stateless, state has to live somewhere else. For data platforms, there are several kinds of state.
Identity state lives in identity providers, tokens, sessions, or delegation services.
Task state lives in the agent host, workflow engine, or durable orchestration layer.
Semantic state lives in metric catalogs, semantic layers, and data product registries.
Table state lives in catalogs and table metadata.
Query state lives in query engines and job histories.
Audit state lives in logs and observability systems.
Approval state lives in workflow systems.
The tool server should connect these states without becoming the hidden owner of them. That makes failures easier to recover from. If one server instance disappears, another can handle the next request because durable systems hold the important context.
This is the real promise of stateless design for analytics: reliability through clear state ownership.
Concrete Tool Examples
A useful analytics MCP server might expose a tool to list certified metrics for a user. That tool would use identity, semantic metadata, and access policy to return only the metrics the user can access.
Another tool might describe a metric. It would return definition, formula, grain, owner, freshness, tests, lineage, and allowed dimensions.
A third tool might run a governed query. It would accept a metric name, filters, and dimensions rather than arbitrary SQL. The query service would enforce policy and return results with provenance.
A fourth tool might check data freshness. It would look at table metadata, pipeline status, and quality checks.
A fifth tool might inspect lineage. It would show upstream tables, transformations, and downstream consumers.
A sixth tool might request an action. It would create a workflow item rather than directly changing a production system.
These tools are deliberately constrained. They help agents do useful work without giving them administrative control over the lakehouse.
Rate Limits and Budgets
Agentic systems need rate limits. A human may ask one question. An agent may ask ten follow-up questions. A poorly designed agent may ask hundreds.
Each tool should have limits based on user, agent identity, cost, data sensitivity, and workflow type. Metadata tools may be cheap. Query tools may be expensive. Action tools may be high risk.
Budgets can be soft or hard. A soft budget warns the agent or user that a workflow is becoming expensive. A hard budget stops execution. High-risk or high-cost tools can require approval.
This is especially important for stateless servers because scaling out is easy. Without budgets, the tool layer may absorb load while the query engine, catalog, or storage layer suffers.
The goal is not to make agents timid. The goal is to make their activity observable and bounded.
Production Readiness Tests
Before exposing MCP-style data tools widely, test failure behavior.
What happens when the semantic layer is unavailable?
What happens when the catalog is slow?
What happens when the query engine rejects a request?
What happens when the user lacks access?
What happens when data is stale?
What happens when the agent retries the same request?
What happens when a tool returns partial results?
What happens when a client requests a protocol version the server does not support?
The answers should be boring. The tool should fail clearly, log durably, and avoid leaking sensitive information.
Human Experience Still Matters
Even in a technical article about stateless MCP servers, the human experience matters. Users need to understand why an agent refused, why a result is delayed, or why a tool requires approval.
A good tool layer should produce explanations that are understandable. “Policy denied” is technically clear but not always useful. A better response might say that the requested metric is restricted at customer-level grain and can be viewed only as an aggregate for the user’s role.
This is another place semantic metadata helps. It lets the system explain policy in business terms.
Treat Released Specs as Contracts
When I first wrote this, the July 28 release was three weeks away, and my advice was to keep production contracts tied to released behavior. The release has now shipped, and the advice carries over: pin each tool server to the protocol versions it has been tested against, advertise them through server/discover, and plan migrations inside the twelve-month deprecation window rather than at the end of it.
This is especially important for enterprise data platforms because tool interfaces become part of governance. If a tool contract changes, audit, policy, and agent behavior may change with it.
Treat drafts as direction. Treat released specs as contracts.
How This Prepares the Agentic Lakehouse
Stateless MCP patterns prepare the Agentic Lakehouse by making the interface layer more scalable and standard. Agents can call tools through a clearer protocol. Platform teams can expose governed capabilities without writing custom integrations for every AI application.
But the value still comes from the lakehouse services underneath. The semantic layer defines meaning. The query layer executes. The catalog governs tables. Iceberg stores table state. Observability records behavior. Workflow systems manage approvals.
The MCP layer should make those services easier to use, not replace them.
Architecture Checklist for Data Teams
Start by listing the data tasks agents should perform. Separate discovery, definition lookup, query execution, validation, lineage, and workflow requests.
For each task, decide whether it should be exposed as an MCP tool, a resource, or not exposed at all.
Define the identity model. Decide how user identity, agent identity, and workload identity will flow into every request.
Define the authorization model. Decide which roles can call each tool and which datasets each tool can touch.
Define the semantic model. Make sure agents can retrieve approved definitions rather than infer them.
Define the query model. Prefer governed metric queries and semantic views over raw SQL for common workflows.
Define the audit model. Every request should have a correlation ID and durable log record.
Define the cost model. Expensive tools need budgets, rate limits, and monitoring.
Define the approval model. Action tools should create controlled workflow requests unless execution has been explicitly approved.
Define the compatibility model. Track which MCP spec version each tool server supports.
This checklist makes MCP adoption a platform decision instead of a connector experiment.
Common Failure Modes
The first failure mode is exposing too much power too early. An arbitrary query tool is easy to build and hard to govern.
The second is treating statelessness as a reason to ignore workflow context. The context still matters. It just should not live only in process memory.
The third is weak identity propagation. If every tool call runs through one broad credential, the architecture loses accountability.
The fourth is inconsistent tool semantics. If two teams expose different definitions of the same metric, agents will inherit the confusion.
The fifth is missing observability. Without traces, teams cannot explain agent behavior.
The sixth is hidden session dependence. Servers ported from the 2025-11-25 revision sometimes keep per-connection state in memory. Under 2026-07-28 that state has to move to explicit handles or durable stores.
These failure modes are preventable when the MCP layer is treated as part of the data platform control surface.
What Changed on July 28, Mapped to Data Platform Concerns
In July I listed what I would inspect on release day. Here is how each item landed in the final spec.
Transport expectations: Streamable HTTP with required Mcp-Method and Mcp-Name headers, and HTTP+SSE deprecated.
Session behavior: no protocol sessions, and explicit handles for state that spans calls.
Authentication guidance: issuer validation, credentials bound to their issuer, and Client ID Metadata Documents preferred over Dynamic Client Registration.
Capability discovery: server/discover, which every server must implement.
Tool result structure: a required resultType field, and full JSON Schema 2020-12 for tool input and output schemas.
Error handling: UnsupportedProtocolVersionError for version mismatches, and a reserved error-code range for the spec itself.
Compatibility: version negotiation on every request, with a documented path for talking to handshake-era servers.
None of these change what a governed data tool should do. They change where state lives and how cheaply a gateway can see what is being called, which is good news for audit, policy, and scaling. Protocol work should improve the control surface, not become an excuse to skip platform design.
Frequently Asked Questions
When was the MCP 2026-07-28 specification released?
The final 2026-07-28 specification was released on July 28, 2026, after a release candidate locked on May 21, 2026. It is the current MCP protocol version, replacing 2025-11-25 as the latest revision.
Is MCP stateless now?
Yes. The 2026-07-28 revision removes the initialize handshake and the Mcp-Session-Id header, and every request carries its protocol version and client capabilities in _meta. Servers that need state across calls mint explicit handles and pass them as ordinary tool arguments.
What replaced the MCP initialize handshake?
Servers must implement a new server/discover method that advertises supported protocol versions, capabilities, and identity. Clients may call it first, or send any request directly and handle an UnsupportedProtocolVersionError if the version is not supported.
Is the HTTP+SSE transport still supported in MCP?
HTTP+SSE is deprecated under the new feature lifecycle policy, and new implementations should use Streamable HTTP. Deprecated features stay in the specification for at least twelve months before they can be removed.
What does stateless MCP change for data platforms?
Any request can land on any server instance, so data tool servers can scale behind an ordinary load balancer. Identity, query jobs, approvals, and audit records have to live in durable systems instead of server memory, and the new Mcp-Method and Mcp-Name headers let gateways meter and rate-limit tools without parsing request bodies.
The Direction of Travel
MCP is important because it can standardize the way agents interact with systems. For data platforms, that standardization is useful only if the underlying services are trustworthy.
The stateless 2026-07-28 revision makes agent tool layers easier to scale, but scale is not enough. The tool layer still needs identity, governance, semantic grounding, query performance, auditability, and cost control.
That is why the Agentic Lakehouse remains the more important architecture. MCP gives agents a doorway. The lakehouse decides whether the room behind that doorway is safe, useful, and governed.
For more of my thinking on data lakehouse and AI architecture, explore my books at books.alexmerced.com. To try a modern Agentic Lakehouse experience, visit dremio.com/get-started.